Oops! Something went wrong while submitting the form.
Start the conversation
Tell us briefly about your organisation and what you're trying to understand. We'll come back to you within one business day.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
No obligation. No sales pitch on the first call. The conversation starts where your questions are.
Do AI Agents in FM Give Different Answers Because of the LLM, or the System Around It?
Published on :
October 1, 2026
by
Anisha Bhattacharjee
Views...
There's an understandable worry about agentic AI in facilities management: ask an agent to investigate the same fault twice, and it may not reach the same decision both times. That matters because decisions made by an agent can influence what gets prioritised, what gets investigated, where resources are sent and what action is taken. Large language models (LLMs) are probabilistic by design. They work with patterns and likely conclusions rather than fixed outputs, so the same input can produce different wording and, under some conditions, different outputs.
But the concern skips a step. An LLM is not a decision system, and an operational AI system shouldn't be judged solely by the model inside it. The decision that comes out is what has to be evaluated.
Why the model alone doesn't make the decision
Hand a model months of BMS data, fault history and work orders and ask what to do, and it can contribute reasoning and summarisation. It can't be expected to carry all the domain-specific reasoning behind an operational decision on its own. An operational decision system is larger than the model, and turning a probabilistic model into something that supports repeatable decisions takes far more than feeding it data and asking a -question. Much of what makes a decision dependable happens before the model is called and after it responds.
So if an agent produces different decisions, the useful question is not simply whether an LLM sits inside it. It is how the system around the model handles that variability, and how reliably the resulting system makes decisions.
What decision consistency should mean in FM
Decision consistency is how reliably a system reaches the same decision when it meets the same or a comparable situation. It doesn't mean identical wording: an agent that explains itself differently but lands on the same decision is doing what you'd hope. It doesn't mean never changing its mind either. If the asset's history or operating conditions have changed, a different decision may be exactly right. The case worth questioning is a different decision when the situation is materially the same and nothing explains the change. That is the question we wanted to examine in our own system.
Why decision consistency matters in FM
Trust in the system
If materially similar situations produce different recommendations without an understandable reason, people have to question which decision to follow. Trust becomes harder to build when users cannot tell whether a change in recommendation reflects a change in the asset or a change in the system. For leadership, that can mean slower adoption and a longer path to realising the return on the AI investment.
The human fallback
When people don't trust an AI recommendation, they compensate by checking it themselves, investigating the fault again or making the decision manually. The AI may still be producing useful outputs, but the organisation remains dependent on the same human-heavy process it was trying to move beyond. The business ends up paying for the AI and for the manual effort, and the shift from reactive to proactive FM that justified the investment may not happen.
Scaling decisions across a portfolio
A level of variation that can be manually checked for a handful of assets becomes much harder to manage across thousands of assets, multiple sites and different teams. For AI to support operations at scale, organisations need to know that materially similar situations are being handled in a reasonably repeatable way. Without that, the effort of checking tends to grow with the portfolio instead of shrinking, and a pilot that worked on a few sites may struggle to become a capability across the estate.
Governance and accountability
Leadership needs to understand what the system decided, why it decided it and why a different decision was made when circumstances changed. Without that visibility, it becomes harder to govern AI-supported decisions, compare performance across sites and measure whether the system is actually improving operations. It also becomes harder to defend those decisions to clients, auditors and boards, whether the question is why one asset was prioritised over another or what evidence informed a budget or capex decision.
The goal isn't for an agent to make the same decision regardless of circumstances. It is to make decisions consistently when the context is materially the same, and to make it clear when and why a decision changes.
What we tested
Whether a system does this is hard to tell from the model alone. So we tested it in our own system, on real faults rather than a theoretical example. We ran repeated live fault investigations through our system and compared the decisions it produced across runs. Specifically, we took two live fault investigations and ran each one three times through the part of the system that assesses the significance of a fault and determines its priority. We then compared the results from each run. The purpose was simple: to see how consistently the system reached the same decision when given the same fault again.
What we found
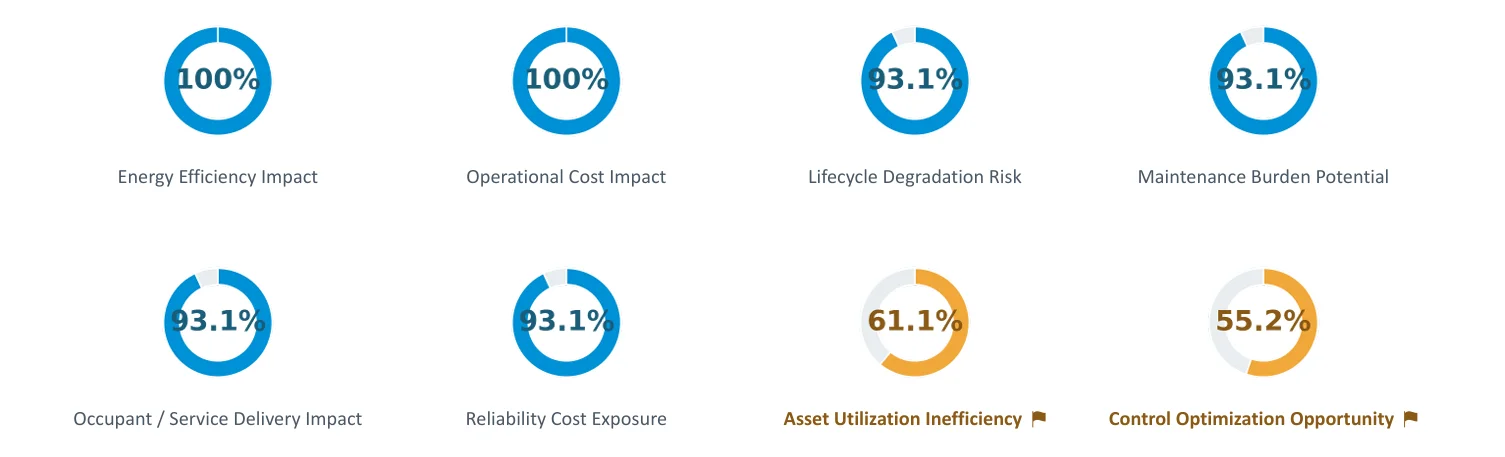
Across the test, the system was highly consistent in most of the areas we assessed. Six of the eight areas showed consistency of 93% or higher, with two reaching 100%. The overall priority assigned to the faults also remained highly consistent, at around 87%.
Consistency by impact area, from Xempla's Decision Consistency Report v1.0.
But the result was not uniform. Two areas showed considerably more variation between runs, with consistency of around 55% and 61%: Control Optimization and Asset Utilization. These were also the only areas where the system's confidence was not consistently high, so it was less sure of itself in the same places its decisions varied.
That variation is important because a different decision is not automatically an error. It can reflect a meaningful change in context, or it can identify an area that deserves closer examination. In this test, the underlying fault was the same, which makes these areas particularly interesting for further testing.
The test also showed that different wording doesn't necessarily mean a different decision. The system could explain the same conclusion differently across runs while the underlying decision remained consistent.
We're not presenting these results as a benchmark or a measure of accuracy. They show how our system behaved under these particular testing conditions, using a small sample of two investigations and six runs. Consistency shows where decisions line up and where they diverge, not whether each one was right, and different systems will behave differently. For us, this is a starting point for further testing, not a final claim.
How to evaluate an agent by its decisions
Because the decision is what matters operationally, you can evaluate an agent by what it decides without needing to inspect the underlying model. Take a fault you know well and look at what the system decides when it's assessed repeatedly, and how often it reaches the same decision. When a decision changes, look at whether the system can explain why, and whether it tells you when it's less sure.
Three questions are useful:
Does it reach the same decision when the relevant context is the same?
When the decision changes, can it explain why?
Does it signal when its confidence is lower?
These are decision questions, and any buyer can ask them.
So when an agent makes a different call the next time it sees the same fault, the useful question isn't simply why LLMs are probabilistic. It's what happened between the data and the decision.
Our Decision Consistency Report is one attempt to look at that question in our own system. It isn't a benchmark or a proposed standard. It is what we found when we put our own system under the microscope, including the areas where it was less consistent.
And that is the more important point. Building useful AI for FM involves more than choosing a capable language model. The model is one part of a much larger system, and how the different pieces work together is a big part of what decides whether the technology can support real operational decisions.
If you're testing or deploying agentic systems in FM, we'd like to hear how you're evaluating them and what you're seeing in your own environments. If you'd like to see the full report
Can an AI agent give different answers to the same question?
Yes. Because language models are probabilistic, an AI agent can produce different wording and, in some cases, different decisions when given the same question or fault more than once. A different answer isn't automatically an unreliable one. What matters is whether the underlying situation and relevant context have changed.
Is a consistent AI decision the same as a correct one?
No. A system can be consistently wrong, so consistency tells you whether it reaches the same decision under the same conditions, not whether the decision is correct. Consistency needs to be considered alongside what actually happened on the asset, such as whether a fault turned out to have the impact the system predicted.
Is AI in facilities management just about large language models?
No. FM decisions draw on many kinds of information, including building system and sensor data, maintenance history and written reports. A language model can contribute to that, but it is one technology among several. Useful FM AI tends to involve different kinds of AI and technology working together, each contributing where it fits.
What should facilities management teams test before relying on an AI agent?
It helps to test how the system behaves with real operational scenarios, not only how it performs in a demonstration. That can mean giving it the same or a materially similar fault more than once and checking whether its decisions hold, seeing how it responds when the context changes, and checking whether it signals when it is less certain. These tests give a clearer picture of how the system is likely to behave once it moves from a controlled demo into live FM operations.